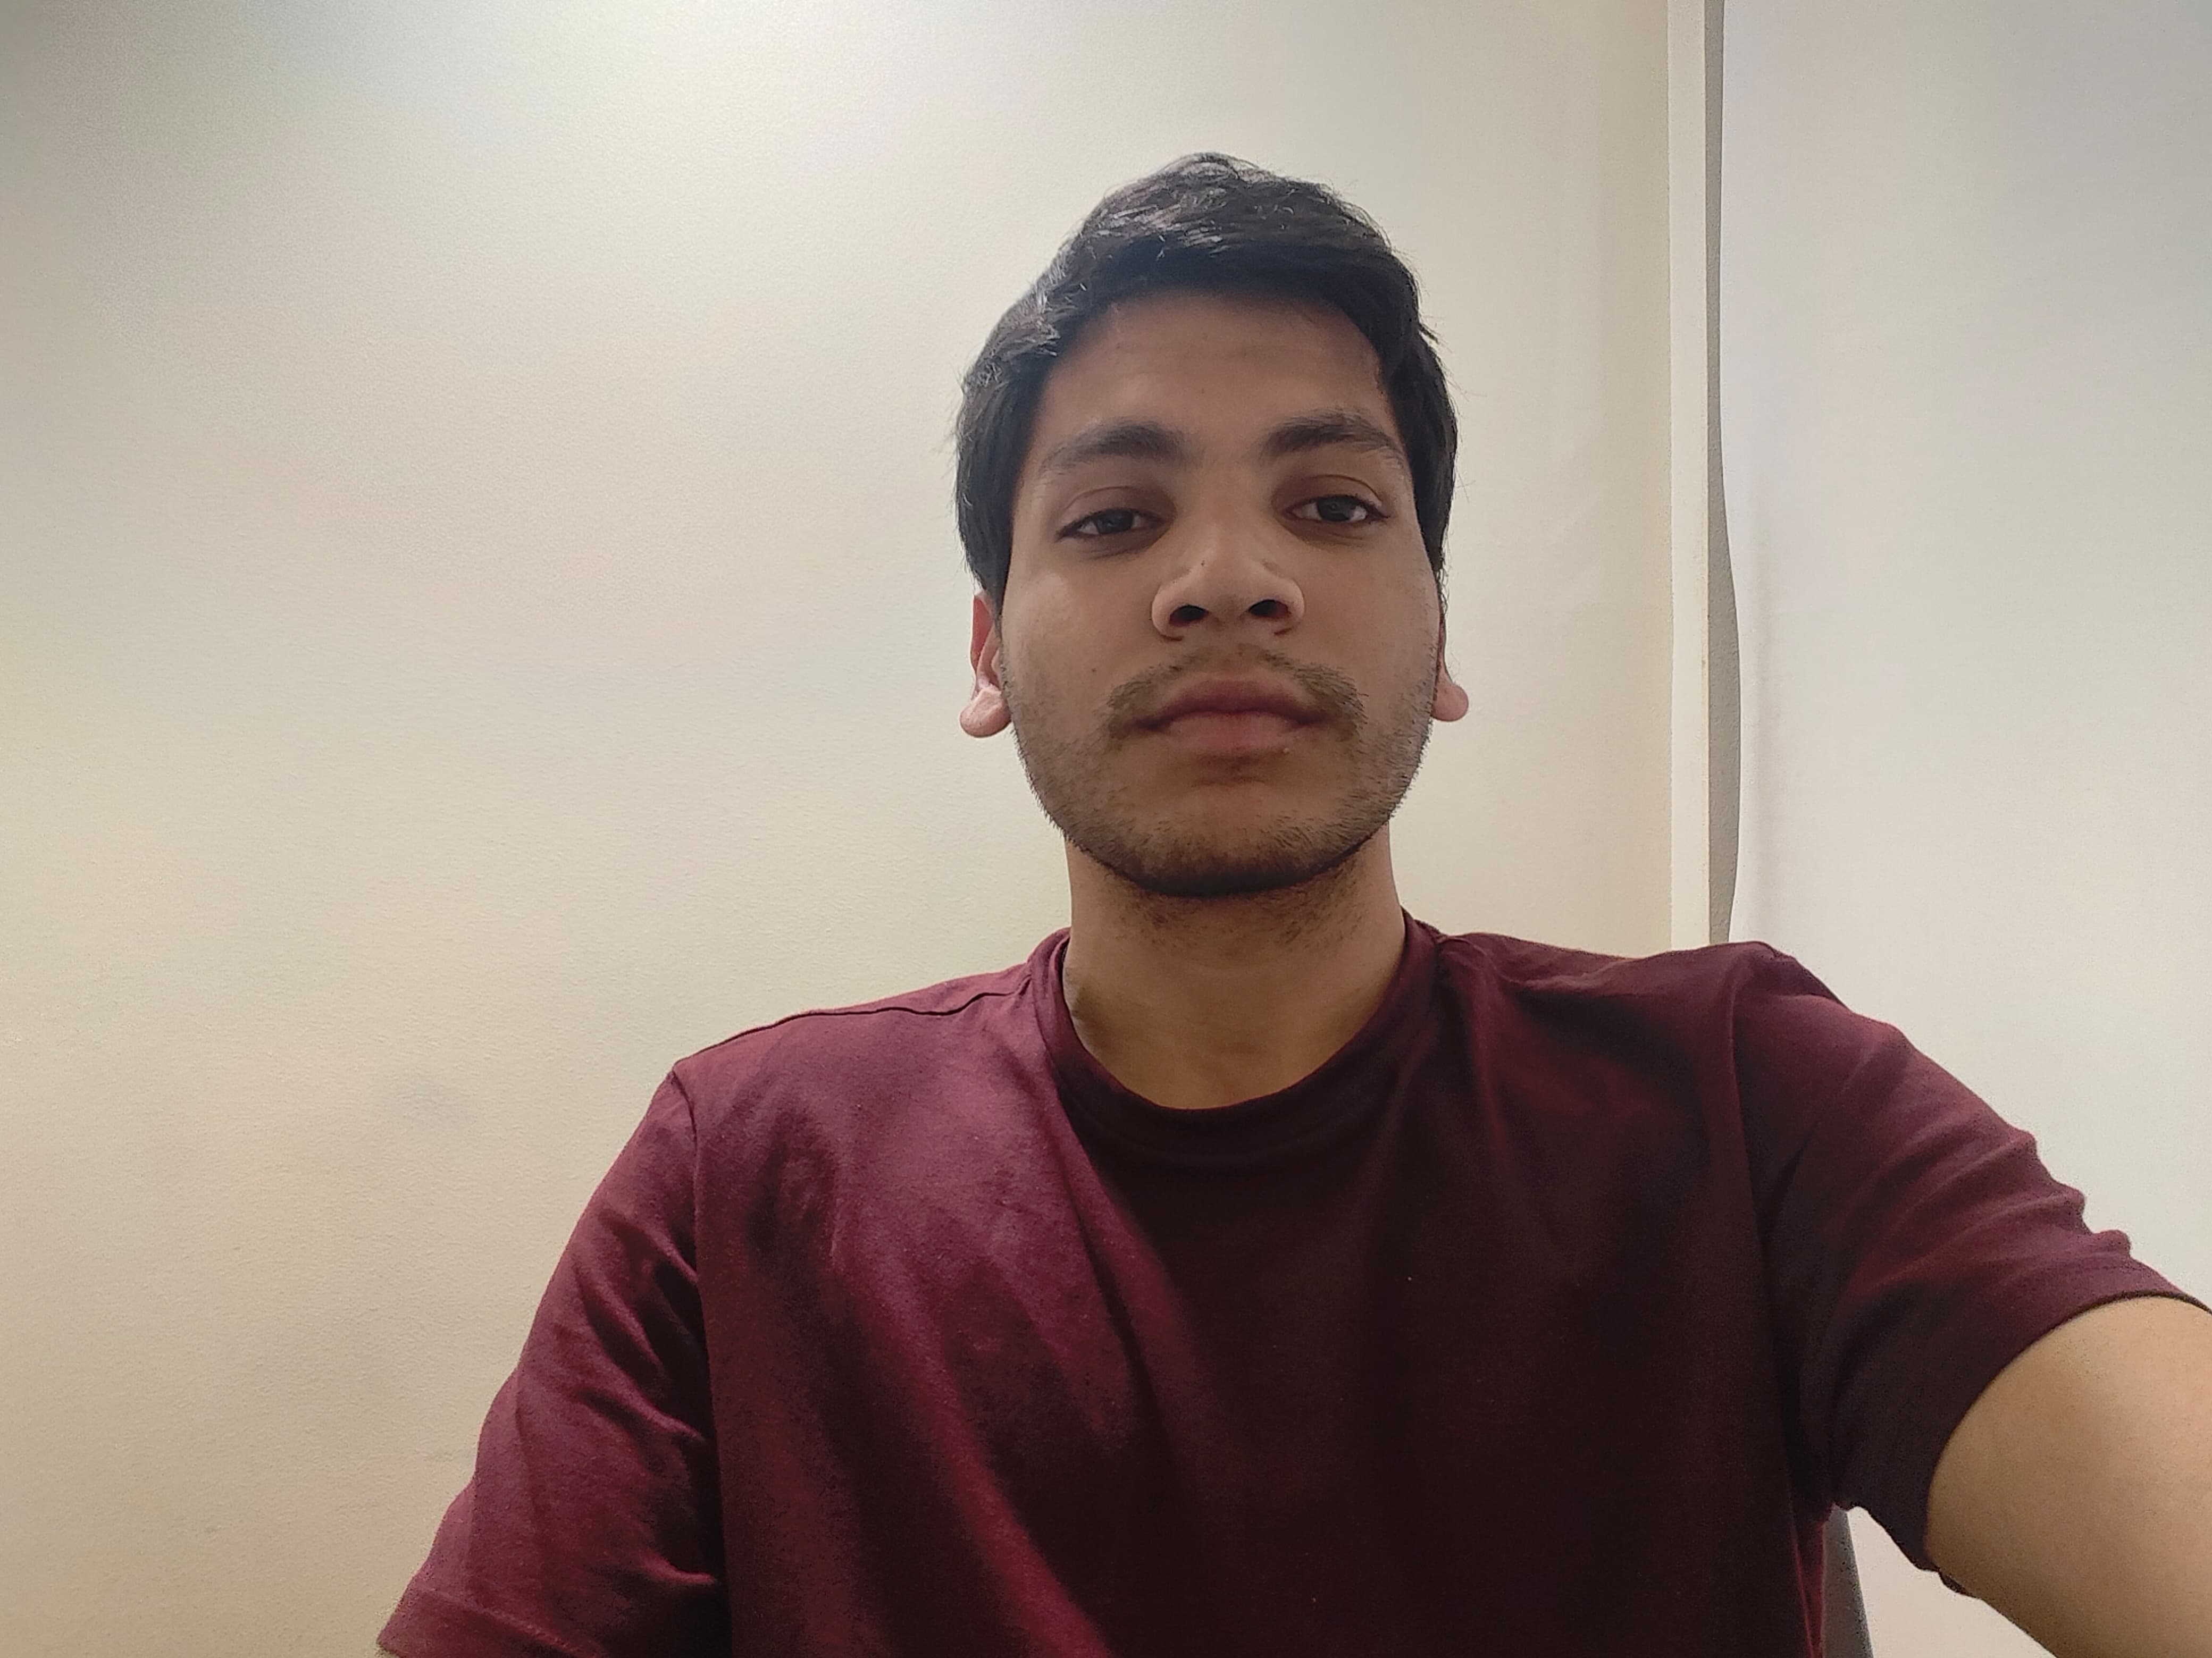
I am a Master's student in the Institute for Computational and Mathematical Engineering (ICME) at Stanford University, specializing in Data Science. My interests lie at the intersection of machine learning, large language models, and intelligent systems, with a particular focus on building efficient, reliable, and capable AI systems.
Previously, I was a Research Fellow at Microsoft Research India in the AI4Code group, where I worked on large language models for code understanding and generation with Dr. Aditya Kanade, Dr. Nagarajan Natarajan, and Dr. Abhijeet Awasthi. My work resulted in publications at ICML, COLM, and ICLR, including work on robust adaptation of code LMs and evaluating models beyond functional correctness.
I have also worked on AI systems in both research and production settings. At Stanford, I am a Graduate Research Assistant with the Crowdsourced Democracy Team, building full-stack infrastructure for civic deliberation experiments. I am currently a Software Engineering Intern at Uber, where I work on Earner Copilot, an LLM-based conversational assistant for drivers and couriers, developing agentic capabilities for diagnosing demand and answering forecasting questions.
My recent coursework at Stanford includes Language Modeling from Scratch, Reinforcement Learning, Natural Language Processing, and Machine Learning with Graphs, complementing my broader interests in foundation models, reinforcement learning, and machine learning systems. I earned my B.Tech. in Mathematics and Computing from IIT Goa, India, in 2023. For more details about my background, see my CV. If you'd like to discuss my work or research interests, feel free to get in touch.
Experience
-- Evaluated direct date-to-weekday mapping, identified LLM reliability issues, and shipped a deterministic tool-based approach for
date-grounded query resolution
-- Integrated real-world events from a 3rd-party API data into demand-forecast answers and fetched map markers in parallel with
the LLM call to hide an additional latency layer
-- Built a ride-diagnostics sub-agent that runs parallel checks to diagnose “why not getting requests?”; migrated high-QPS checks
from Python to Go for reuse by proactive driver nudges and wired them into the full conversational flow
-- Co-authored NextCoder (ICML 2025, DL4C @ ICLR 2025): designed synthetic-data pipeline for instruction tuning to generate
250k code-editing instances using GPT-4 and Llama-3 to save the API cost and a robust adaptation method for 7B–32B
parameter code LMs across diverse code-editing tasks, achieving 10–20% absolute gains over Qwen2.5-Coder baselines
-- Built NoFunEval (COLM 2024), a multilingual benchmark evaluating LMs on non-functional aspects (latency, security, etc.)
-- Automated process of allocating drivers optimally to Metro trains by formulating constraints in Gurobipy solver.
-- Restructured the problem using Max Flows reducing timetable preparation time from few days to a few seconds.
-- Deployed the algorithm in Bengaluru Metro Rail Corporation Limited (BMRCL).
-- Contributed to the backend of the Questa compiler in C, optimized coverage calculations to achieve a 3x improvement.
-- Designed 50+ test cases, identifying and resolving 10+ JIRA issues, significantly improving the system reliability.

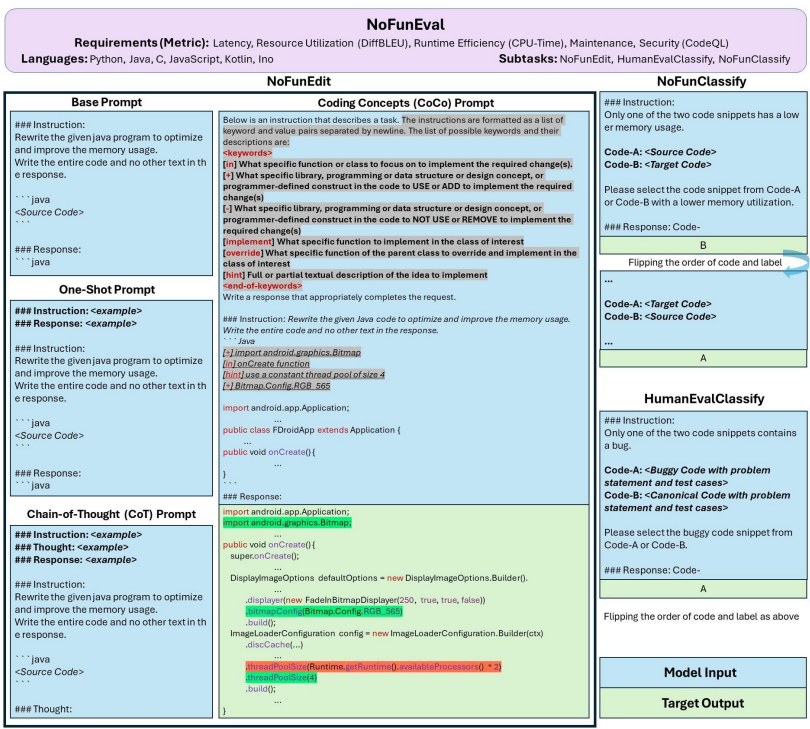
NoFunEval: Funny How Code LMs Falter on Requirements Beyond Functional Correctness
Manav Singhal, , Abhijeet Awasthi, Nagarajan Natarajan, Aditya Kanade
COLM'24 PDF
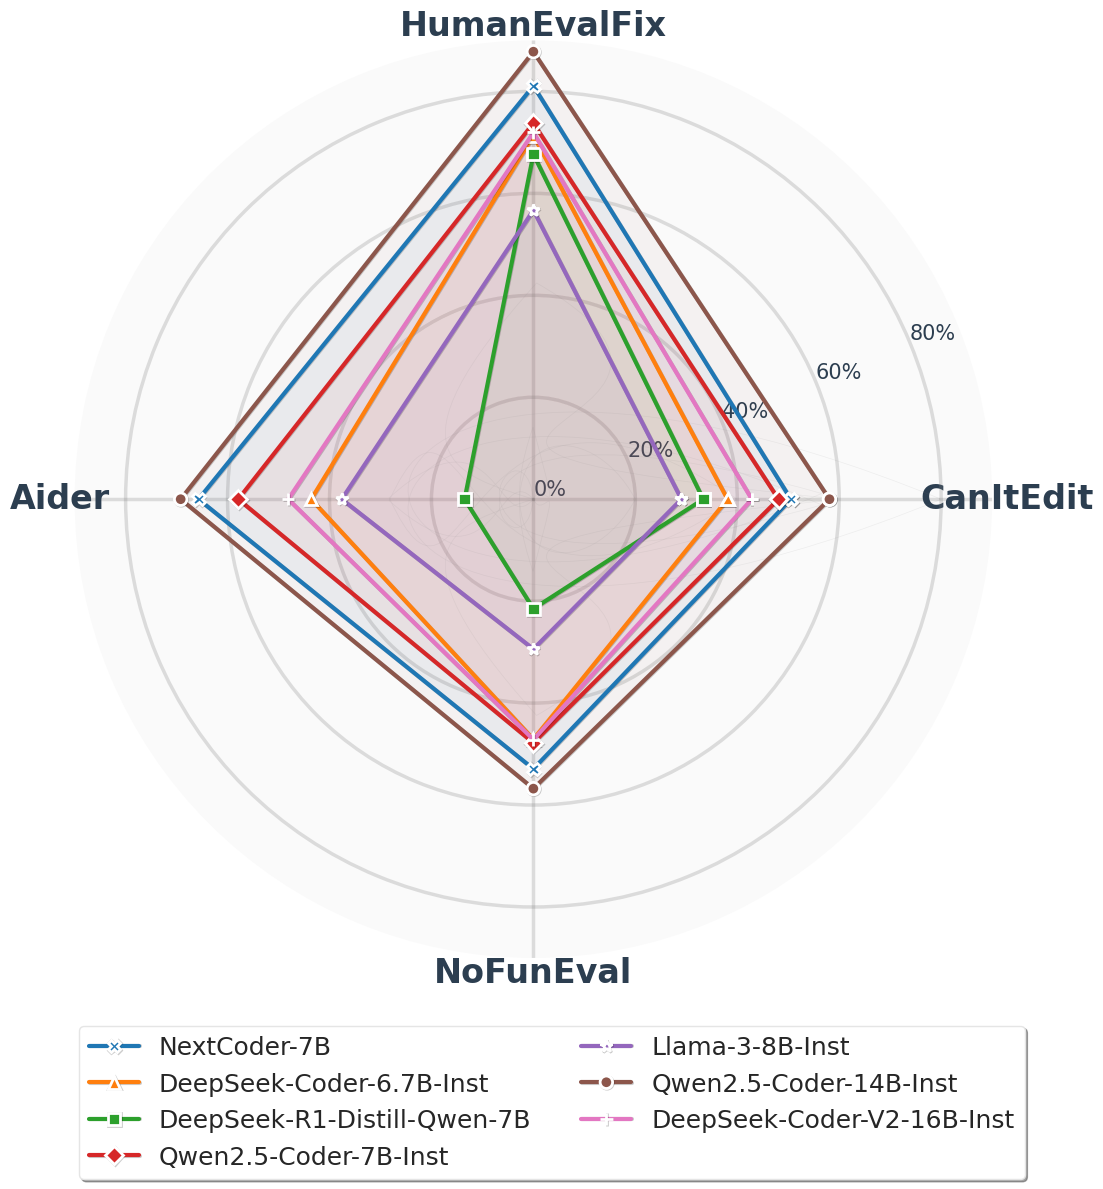
Robust Learning of Diverse Code Edits
, Swayam Singh, Abhijeet Awasthi, Aditya Kanade, Nagarajan Natarajan
DL4C @ ICLR'25, ICML'25 PDF
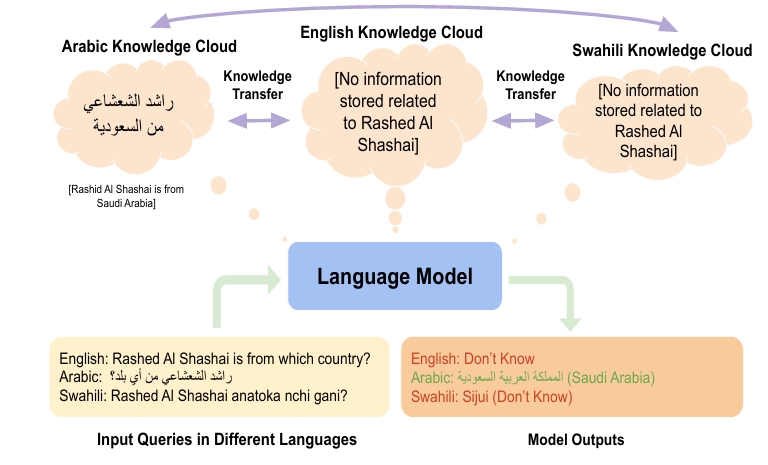
Language Models' Factuality Depends on the Language of Inquiry
, Kumar Tanmay, Ayush Agrawal, Kumar Ayush, Hamid Palangi, Paul Pu Liang
Arxiv Preprint PDF
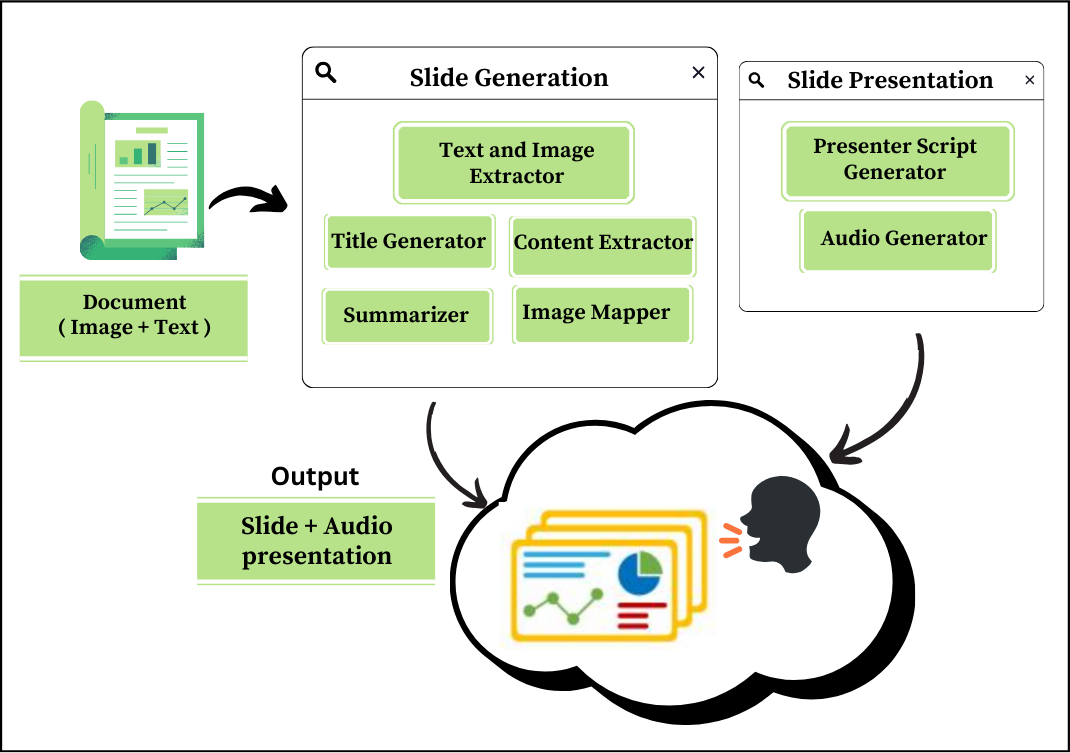
PASS: Presentation Automation for Slide Generation and Speech
, Aarohi Bhand
Arxiv Preprint PDF